<?xml version="1.0" encoding="UTF-8"?>
<feed xmlns="http://www.w3.org/2005/Atom">
  <title><![CDATA[Jake McCrary's articles on google]]></title>
  <link href="https://jakemccrary.com/atom.xml" rel="self"/>
  <link href="https://jakemccrary.com/"/>
  <updated>2026-08-17T20:14:29+00:00</updated>
  <id>https://jakemccrary.com/</id>
  <author>
    <name><![CDATA[Jake McCrary]]></name>
  </author>
  <entry>
    <id>https://jakemccrary.com/blog/2017/04/17/what-are-the-most-used-clojure-libraries/index.html</id>
    <link href="https://jakemccrary.com/blog/2017/04/17/what-are-the-most-used-clojure-libraries/index.html"/>
    <title><![CDATA[What are the most used Clojure libraries?]]></title>
    <updated>2017-04-17T23:59:59+00:00</updated>
    <content type="html"><![CDATA[<div><p>In a <a href="/blog/2017/03/31/what-clojure-testing-library-is-most-used/">previous post</a>, we used Google&apos;s BigQuery and the public <a href="https://cloud.google.com/bigquery/public-data/github">GitHub dataset</a> to discover the most used Clojure testing library. The answer wasn&apos;t surprising. The built-in <code>clojure.test</code> was by far the most used.</p><p>Let&apos;s use the dataset to answer a less obvious question, what are the most used libraries in Clojure projects? We&apos;ll measure this by counting references to libraries in <code>project.clj</code> and <code>build.boot</code> files.</p><p>Before we can answer that question, we&apos;ll need to transform the data. First, we create the Clojure subset of the GitHub dataset. I did this by executing the following queries and saving the results to tables<a href="#fn-1" id="fnref1"><sup>1</sup></a>.</p><pre><code class="language-sql">-- Save the results of this query to the clojure.files table
SELECT
  *
FROM
  [bigquery-public-data:github_repos.files]
WHERE
  RIGHT(path, 4) = &apos;.clj&apos;
  OR RIGHT(path, 5) = &apos;.cljc&apos;
  OR RIGHT(path, 5) = &apos;.cljs&apos;
  OR RIGHT(path, 10) = &apos;boot.build&apos;

-- Save the results to clojure.contents
SELECT *
FROM [bigquery-public-data:github_repos.contents]
WHERE id IN (SELECT id FROM clojure.files)
</code></pre><p>Next we extract the dependencies from <code>build.boot</code> and <code>project.clj</code> files. Fortunately for us, both of these files specify dependencies in the same format, so we&apos;re able to use the same regular expression on both types.</p><p>The query below identifies <code>project.clj</code> and <code>build.boot</code> files, splits each file into lines, and extracts referenced library names and versions using a regular expression. Additional filtering is done get rid of some spurious results.</p><pre><code class="language-sql">SELECT
  REGEXP_EXTRACT(line, r&apos;\[+(\S+)\s+&quot;\S+&quot;]&apos;) AS library,
  REGEXP_EXTRACT(line, r&apos;\[+\S+\s+&quot;(\S+)&quot;]&apos;) AS version, 
  COUNT(*) AS count
FROM (
  SELECT
    SPLIT(content, &apos;\n&apos;) AS line
  FROM
    [clojure.contents]
  WHERE
    id IN (
    SELECT
      id
    FROM
      [clojure.files]
    WHERE
      path LIKE &apos;%project.clj&apos;
      OR path LIKE &apos;%build.boot&apos;)
      HAVING line contains &apos;[&apos;)
GROUP BY
  library, version
HAVING library is not null and not library contains &apos;&quot;&apos;
ORDER BY
  count DESC
</code></pre><p>The first five rows from the result are below. Let&apos;s save the entire result to a <code>clojure.libraries</code> table.</p><pre><code>| library             | version | count |
|---------------------+---------+-------|
| org.clojure/clojure | 1.6.0   | 7015  |
| org.clojure/clojure | 1.5.1   | 4251  |
| org.clojure/clojure | 1.7.0   | 4093  |
| org.clojure/clojure | 1.8.0   | 3016  |
| hiccup              | 1.0.5   | 1280  |
</code></pre><p>Now we can start answering all sorts of interesting questions.</p><p>What is the most referenced library put out under the <code>org.clojure</code> group?</p><pre><code>SELECT library, sum(count) count
FROM clojure.libraries
WHERE library CONTAINS &apos;org.clojure&apos;
GROUP BY library
ORDER BY count desc

| Row | library                        | count |
|-----+--------------------------------+-------|
|   1 | org.clojure/clojure            | 20834 |
|   2 | org.clojure/clojurescript      |  3080 |
|   3 | org.clojure/core.async         |  2612 |
|   4 | org.clojure/tools.logging      |  1579 |
|   5 | org.clojure/data.json          |  1546 |
|   6 | org.clojure/tools.nrepl        |  1244 |
|   7 | org.clojure/java.jdbc          |  1064 |
|   8 | org.clojure/tools.cli          |  1053 |
|   9 | org.clojure/tools.namespace    |   982 |
|  10 | org.clojure/test.check         |   603 |
|  11 | org.clojure/core.match         |   578 |
|  12 | org.clojure/math.numeric-tower |   503 |
|  13 | org.clojure/data.csv           |   381 |
|  14 | org.clojure/math.combinatorics |   372 |
|  15 | org.clojure/tools.reader       |   368 |
|  16 | org.clojure/clojure-contrib    |   335 |
|  17 | org.clojure/data.xml           |   289 |
|  18 | org.clojure/tools.trace        |   236 |
|  19 | org.clojure/java.classpath     |   199 |
|  20 | org.clojure/core.cache         |   179 |
</code></pre><p>Clojure and ClojureScript are at the top, which isn&apos;t surprising. I&apos;m surprised to see <code>tools.nrepl</code> in the next five results (rows 3-7). It is the only library out of the top that I haven&apos;t used.</p><p>What testing library is used the most? We already answered this in my <a href="/blog/2017/03/31/what-clojure-testing-library-is-most-used/">last article</a> but let&apos;s see if we get the same answer when we&apos;re counting how many times a library is pulled into a project.</p><pre><code>SELECT library, sum(count) count
FROM [clojure.libraries] 
WHERE library in (&apos;midje&apos;, &apos;expectations&apos;, &apos;speclj&apos;, &apos;smidjen&apos;, &apos;fudje&apos;)
GROUP BY library
ORDER BY count desc

| Row | library                | count |
|-----+------------------------+-------|
|   1 | midje                  |  1122 |
|   2 | speclj                 |   336 |
|   3 | expectations           |   235 |
|   4 | smidjen                |     1 |
</code></pre><p>Those results are close to the previous results. Of the non-clojure.test libraries, midje still ends up on top.</p><p>What groups (as identified by the Maven groupId) have their libraries referenced the most? Top 12 are below but the <a href="https://docs.google.com/a/jakemccrary.com/spreadsheets/d/1QGRRGSo5t5Pnpwizdv_H8negs8NBxtRour6KxWN6hVY/edit?usp=sharing">full result</a> is available.</p><pre><code>SELECT REGEXP_EXTRACT(library, r&apos;(\S+)/\S+&apos;) AS group, sum(count) AS count
FROM [clojure.libraries]
GROUP BY group
HAVING group IS NOT null
ORDER BY count DESC

| Row | group                 | count |
|-----+-----------------------+-------|
|   1 | org.clojure           | 39611 |
|   2 | ring                  |  5817 |
|   3 | com.cemerick          |  2053 |
|   4 | com.taoensso          |  1605 |
|   5 | prismatic             |  1398 |
|   6 | org.slf4j             |  1209 |
|   7 | cljsjs                |   868 |
|   8 | javax.servlet         |   786 |
|   9 | com.stuartsierra      |   642 |
|  10 | com.badlogicgames.gdx |   586 |
|  11 | cider                 |   560 |
|  12 | pjstadig              |   536 |
</code></pre><p>And finally, the question that inspired this article, what is the most used library?</p><pre><code>SELECT library, sum(count) count
FROM [clojure.libraries]
WHERE library != &apos;org.clojure/clojure&apos;
GROUP BY library
ORDER BY count desc

| Row | library                     | count |
|-----+-----------------------------+-------|
|   1 | compojure                   |  3609 |
|   2 | lein-cljsbuild              |  3413 |
|   3 | org.clojure/clojurescript   |  3080 |
|   4 | org.clojure/core.async      |  2612 |
|   5 | lein-ring                   |  1809 |
|   6 | cheshire                    |  1802 |
|   7 | environ                     |  1763 |
|   8 | ring                        |  1678 |
|   9 | clj-http                    |  1648 |
|  10 | clj-time                    |  1613 |
|  11 | hiccup                      |  1591 |
|  12 | lein-figwheel               |  1582 |
|  13 | org.clojure/tools.logging   |  1579 |
|  14 | org.clojure/data.json       |  1546 |
|  15 | http-kit                    |  1423 |
|  16 | lein-environ                |  1325 |
|  17 | ring/ring-defaults          |  1302 |
|  18 | org.clojure/tools.nrepl     |  1244 |
|  19 | midje                       |  1122 |
|  20 | com.cemerick/piggieback     |  1096 |
|  21 | org.clojure/java.jdbc       |  1064 |
|  22 | org.clojure/tools.cli       |  1053 |
|  23 | enlive                      |  1001 |
|  24 | ring/ring-core              |   995 |
|  25 | org.clojure/tools.namespace |   982 |
</code></pre><p><a href="https://github.com/weavejester/compojure">Compojure</a> takes the top slot. <a href="https://docs.google.com/a/jakemccrary.com/spreadsheets/d/1-zmcOVPKLGrdRT_VkTrRUuRFyuxxmXi9eeH6Xzlt7yg/edit?usp=sharing">Full results are available</a>.</p><p>Before doing this research I tried to predict what libraries I&apos;d see in the top 10. I thought that clj-time and clj-http would be up there. I&apos;m happy to see my guess was correct.</p><p>It was pretty pleasant using BigQuery to do this analysis. Queries took at most seconds to execute. This quick feedback let me play around in the web interface without feeling like I was waiting for computers to do work. This made the research into Clojure library usage painless and fun.</p><ol class="footnotes"><li class="footnote" id="fn-1"><p>I did this in early March 2017.<a href="#fnref1">↩</a></p></li></ol></div>]]></content>
  </entry>
  <entry>
    <id>https://jakemccrary.com/blog/2017/03/31/what-clojure-testing-library-is-most-used/index.html</id>
    <link href="https://jakemccrary.com/blog/2017/03/31/what-clojure-testing-library-is-most-used/index.html"/>
    <title><![CDATA[Which Clojure testing library is most used?]]></title>
    <updated>2017-03-31T23:59:59+00:00</updated>
    <content type="html"><![CDATA[<div><p>I&apos;ve always assumed that the built-in <code>clojure.test</code> is the most widely used testing library in the Clojure community. Earlier this month I decided to test this assumption using the Google&apos;s BigQuery <a href="https://cloud.google.com/bigquery/public-data/github">GitHub dataset</a>.</p><p>The BigQuery GitHub dataset contains over three terabytes of source code from more than 2.8 million open source GitHub repositories. BigQuery lets us quickly query this data using SQL.</p><p>Below is a table with the results (done in early March 2017) of my investigation. Surprising no one, <code>clojure.test</code> comes out as the winner and it is a winner by a lot.</p><pre><code>| Library      | # Repos Using |
|--------------+---------------|
| clojure.test |         14304 |
| midje        |          1348 |
| expectations |           429 |
| speclj       |           207 |
| smidjen      |             1 |
| fudje        |             1 |
</code></pre><p>23,243 repositories were identified as containing Clojure (or ClojureScript) code. This means there were about 6,953 repositories that didn&apos;t use any testing library<a href="#fn-1" id="fnref1"><sup>1</sup></a>. This puts the &quot;no tests or an obscure other way of testing&quot; in a pretty solid second place.</p><p>You should take these numbers as ballpark figures and not exact answers. I know from using GitHub&apos;s search interface that there are three public projects using <a href="https://github.com/jimpil/fudje">fudje</a><a href="#fn-2" id="fnref2"><sup>2</sup></a>.</p><p>So, why don&apos;t all three of those projects show up? The dataset only includes projects where Google could identify the project as open source and the GitHub licenses API is used to do that<a href="#fn-3" id="fnref3"><sup>3</sup></a>. Two of those three projects were probably unable to be identified as something with an appropriate license.</p><p>Another small problem is that since <code>expectations</code> is an actual word, it shows up outside of <code>ns</code> declarations. I ended up using a fairly simple query to generate this data and it only knows that <code>expectations</code> shows up somewhere in a file. I experimented with some more restrictive queries but they didn&apos;t drastically change the result and I wasn&apos;t sure they weren&apos;t wrong in other ways. If you subtract a number between 100 and 150 you&apos;ll probably have a more accurate expectations usage count.</p><p>Keep reading if you want to hear more about the steps to come up with the above numbers.</p><p>If you have other Clojure questions you think could be answered by querying this dataset, let me know in the comments or on <a href="https://twitter.com/jakemcc">twitter</a>. I have some more ideas, so I wouldn&apos;t be surprised if at least one more article gets written.</p><h2 id="the-details">The Details</h2><p>The process was pretty straightforward. Most of my time was spent exploring the tables, figuring out what the columns represented, figuring out what queries worked well, and manually confirming some of the results. BigQuery is very fast. Very little of my time was spent waiting for results.</p><h3 id="1.-setup-the-data">1. Setup the data</h3><p>You get 1 TB of free BigQuery usage a month. You can blow through this in a single query. Google provides sample tables that contain less data but I wanted to operate on the full set of Clojure(Script) files, so my first step was to execute some queries to create tables that only contained Clojure data.</p><p>First, I queried the <code>github_repos.files</code> table for all the Clojure(Script) files and saved that to a <code>clojure.files</code> table.</p><pre><code class="language-sql">SELECT
  *
FROM
  [bigquery-public-data:github_repos.files]
WHERE
  (RIGHT(path, 4) = &apos;.clj&apos;
    OR RIGHT(path, 5) = &apos;.cljc&apos;
    OR RIGHT(path, 5) = &apos;.cljs&apos;)
</code></pre><p>The above query took only 9.2 seconds to run and processed 328 GB of data.</p><p>Using the <code>clojure.files</code> table, we can select the source for all the Clojure code from the <code>github_repos.contents</code>. I saved this to a <code>clojure.contents</code> table.</p><pre><code class="language-sql">SELECT *
FROM [bigquery-public-data:github_repos.contents]
WHERE id IN (SELECT id FROM clojure.files)
</code></pre><p>This query processed 1.84 TB of data in 21.5 seconds. So fast. In just under 30 seconds, I&apos;ve blown through the free limit.</p><h3 id="2.-identify-what-testing-library-(or-libraries)-a-repo-uses">2. Identify what testing library (or libraries) a repo uses</h3><p>We can guess that a file uses a testing library if it contains certain string. The strings we&apos;ll search for are the namespaces we&apos;d expect to see required or used in a <code>ns</code> declaration. The below query does this for each file and then rolls up the results by repository. It took 3 seconds to run and processed 611 MB of data.</p><pre><code>SELECT
  files.repo_name,
  MAX(uses_clojure_test) uses_clojure_test,
  MAX(uses_expectations) uses_expectations,
  MAX(uses_midje) uses_midje,
  MAX(uses_speclj) uses_speclj,
  MAX(uses_fudje) uses_fudje,
  MAX(uses_smidjen) uses_smidjen,
FROM (
  SELECT
    id,
    contents.content LIKE &apos;%clojure.test%&apos; uses_clojure_test,
    contents.content LIKE &apos;%expectations%&apos; uses_expectations,
    contents.content LIKE &apos;%midje%&apos; uses_midje,
    contents.content LIKE &apos;%speclj%&apos; uses_speclj,
    contents.content LIKE &apos;%fudje%&apos; uses_fudje,
    contents.content LIKE &apos;%smidjen%&apos; uses_smidjen,
  FROM
    clojure.contents AS contents) x
JOIN
  clojure.files files ON files.id = x.id
GROUP BY
  files.repo_name
</code></pre><p>Below is a screenshot of the first few rows in the result.</p><p><img alt="BigQuery results for test library usage by repo" src="/images/bigquery-testing-library-result.png" title="BigQuery results for test library usage by repo" /></p><h3 id="3.-export-the-data">3. Export the data</h3><p>At this point, we could continue doing the analysis using SQL and the BigQuery UI but I opted to explore the data using Clojure and the repl. There were too many rows to directly download the query results as a csv file, so I ended up having to save the results as a table and then export it to Google&apos;s cloud storage and download from there.</p><p>The first few rows of the file look like this:</p><pre><code>files_repo_name,uses_clojure_test,uses_expectations,uses_midje,uses_speclj,uses_fudje,uses_smidjen
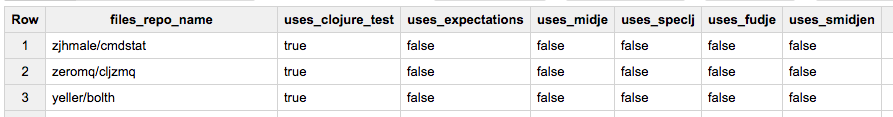
wangchunyang/clojure-liberator-examples,true,false,false,false,false,false
yantonov/rex,false,false,false,false,false,false
</code></pre><h3 id="4.-calculate-some-numbers">4. Calculate some numbers</h3><p>The code takes the csv file and does some transformations. You could do this in Excel or using any language of your choice. I&apos;m not going to include code here, as it isn&apos;t that interesting.</p><h2 id="bigquery-thoughts">BigQuery thoughts</h2><p>This was my first time using Google&apos;s BigQuery. This wasn&apos;t the most difficult analysis to do but I was impressed at the speed and ease of use. The web UI, which I used entirely for this, is neither really great or extremely terrible. It mostly just worked and I rarely had to look up documentation.</p><p>I don&apos;t really feel comfortable making a judgment call on if the cost is expensive or not but this article cost a bit less than seven dollars to write. This doesn&apos;t seem too outrageous to me.</p><p>Based on my limited usage of BigQuery, it is something I&apos;d look into further if I needed its capabilities.</p><ol class="footnotes"><li class="footnote" id="fn-1"><p>Probably higher, as projects can and use more than one testing library.<a href="#fnref1">↩</a></p></li><li class="footnote" id="fn-2"><p>And those projects are <a href="https://github.com/jumarko/clojure-random">jumarko/clojure-random</a>, <a href="https://github.com/dpassen1/great-sort">dpassen1/great-sort</a>, and <a href="https://github.com/jimpil/fudje">jimpil/fudje</a>.<a href="#fnref2">↩</a></p></li><li class="footnote" id="fn-3"><p><a href="https://news.ycombinator.com/item?id=12004644">Source is a Google Developer Advocate&apos;s response on old HN post</a><a href="#fnref3">↩</a></p></li></ol></div>]]></content>
  </entry>
</feed>